Three bets totaling about $173 were placed before news outlets reported Zacharia’s pick and are expected to pay out roughly $9,600 combined.
 Live Chat
Three bets totaling about $173 were placed before news outlets reported Zacharia’s pick and are expected to pay out roughly $9,600 combined.
We’re extending Claude Fable 5 access on all paid plans, as well as keeping Claude Code’s weekly rate limits 50% higher, through July 19.
— Claude (@claudeai) July 12, 2026
Creative writing
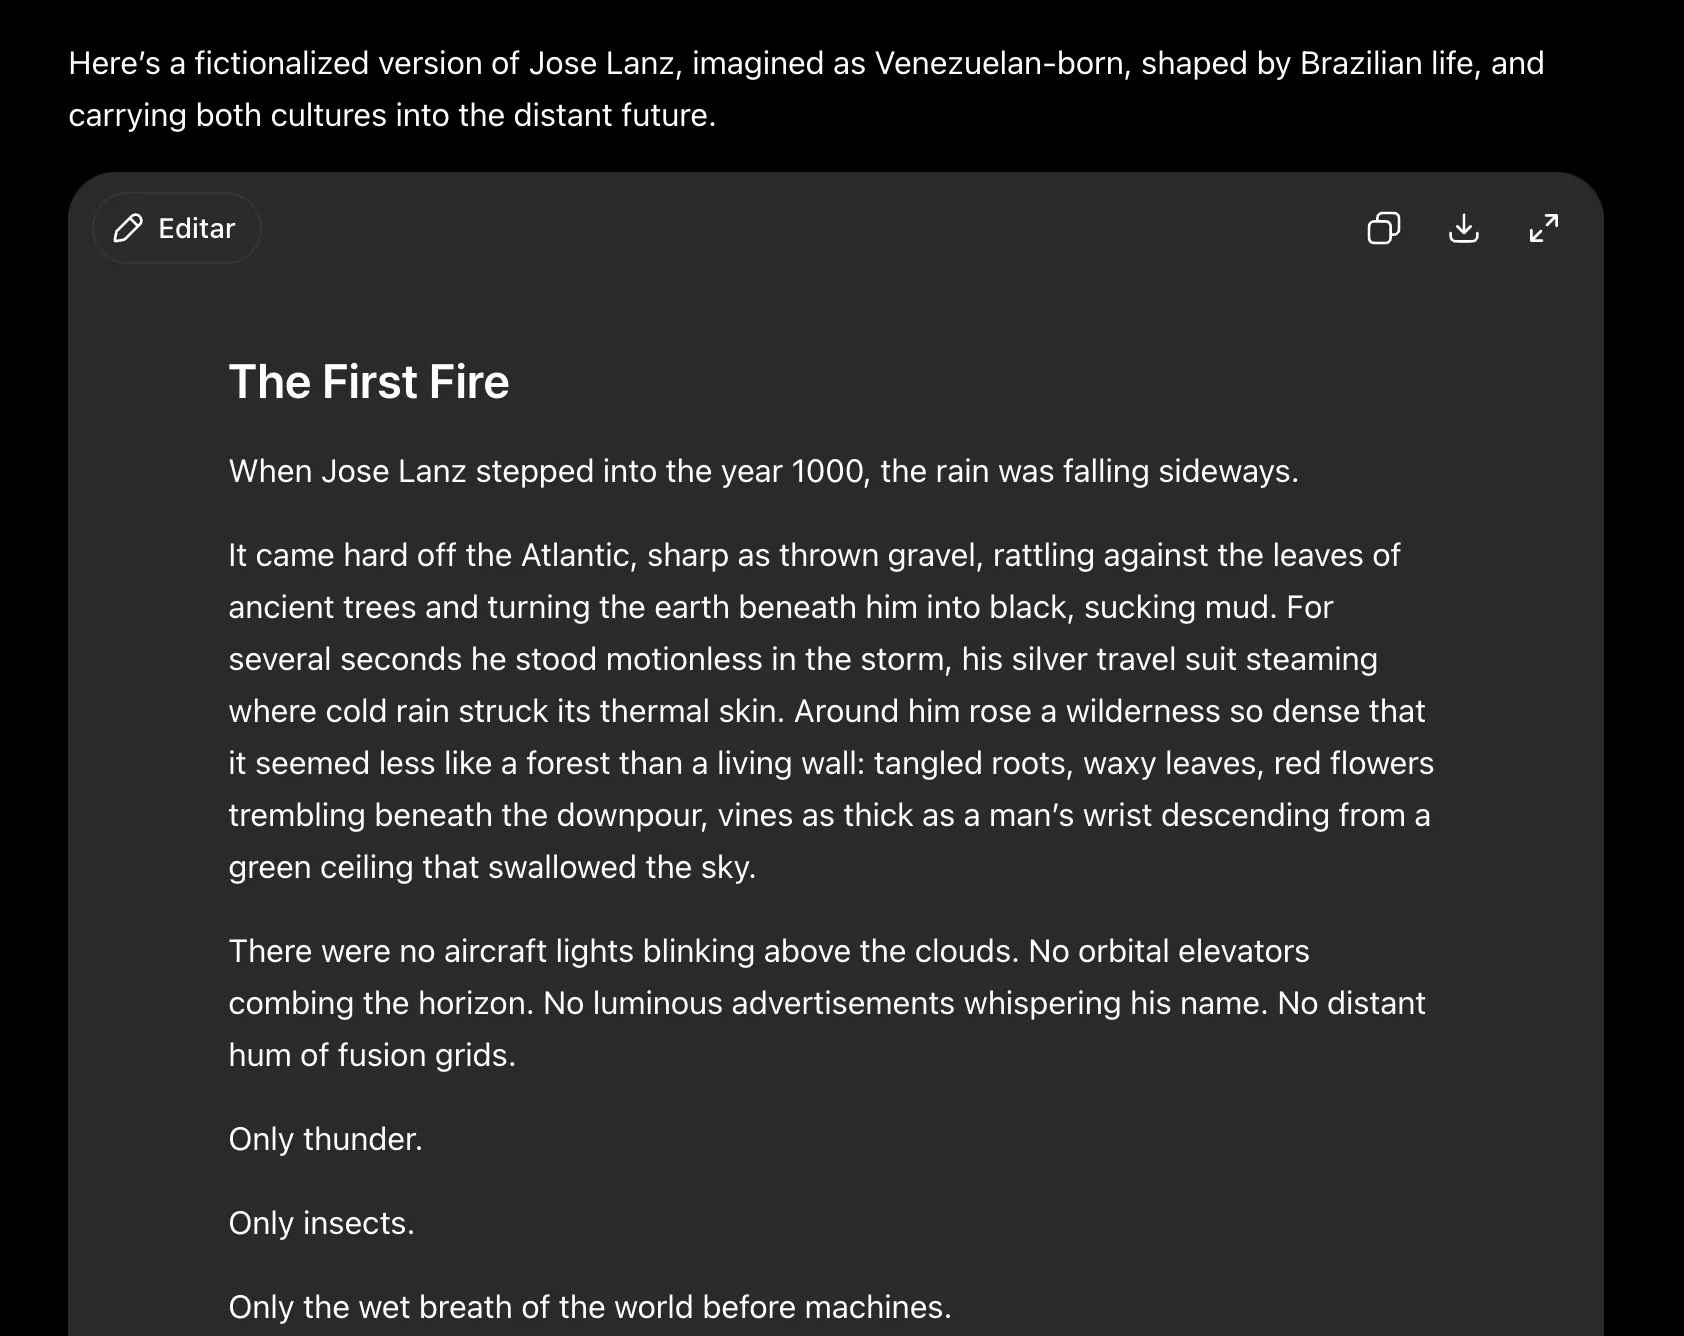
Associative thinking: A twig, a class argument, a lettuce
Logic and non-math reasoning: The bridge puzzle, rewritten
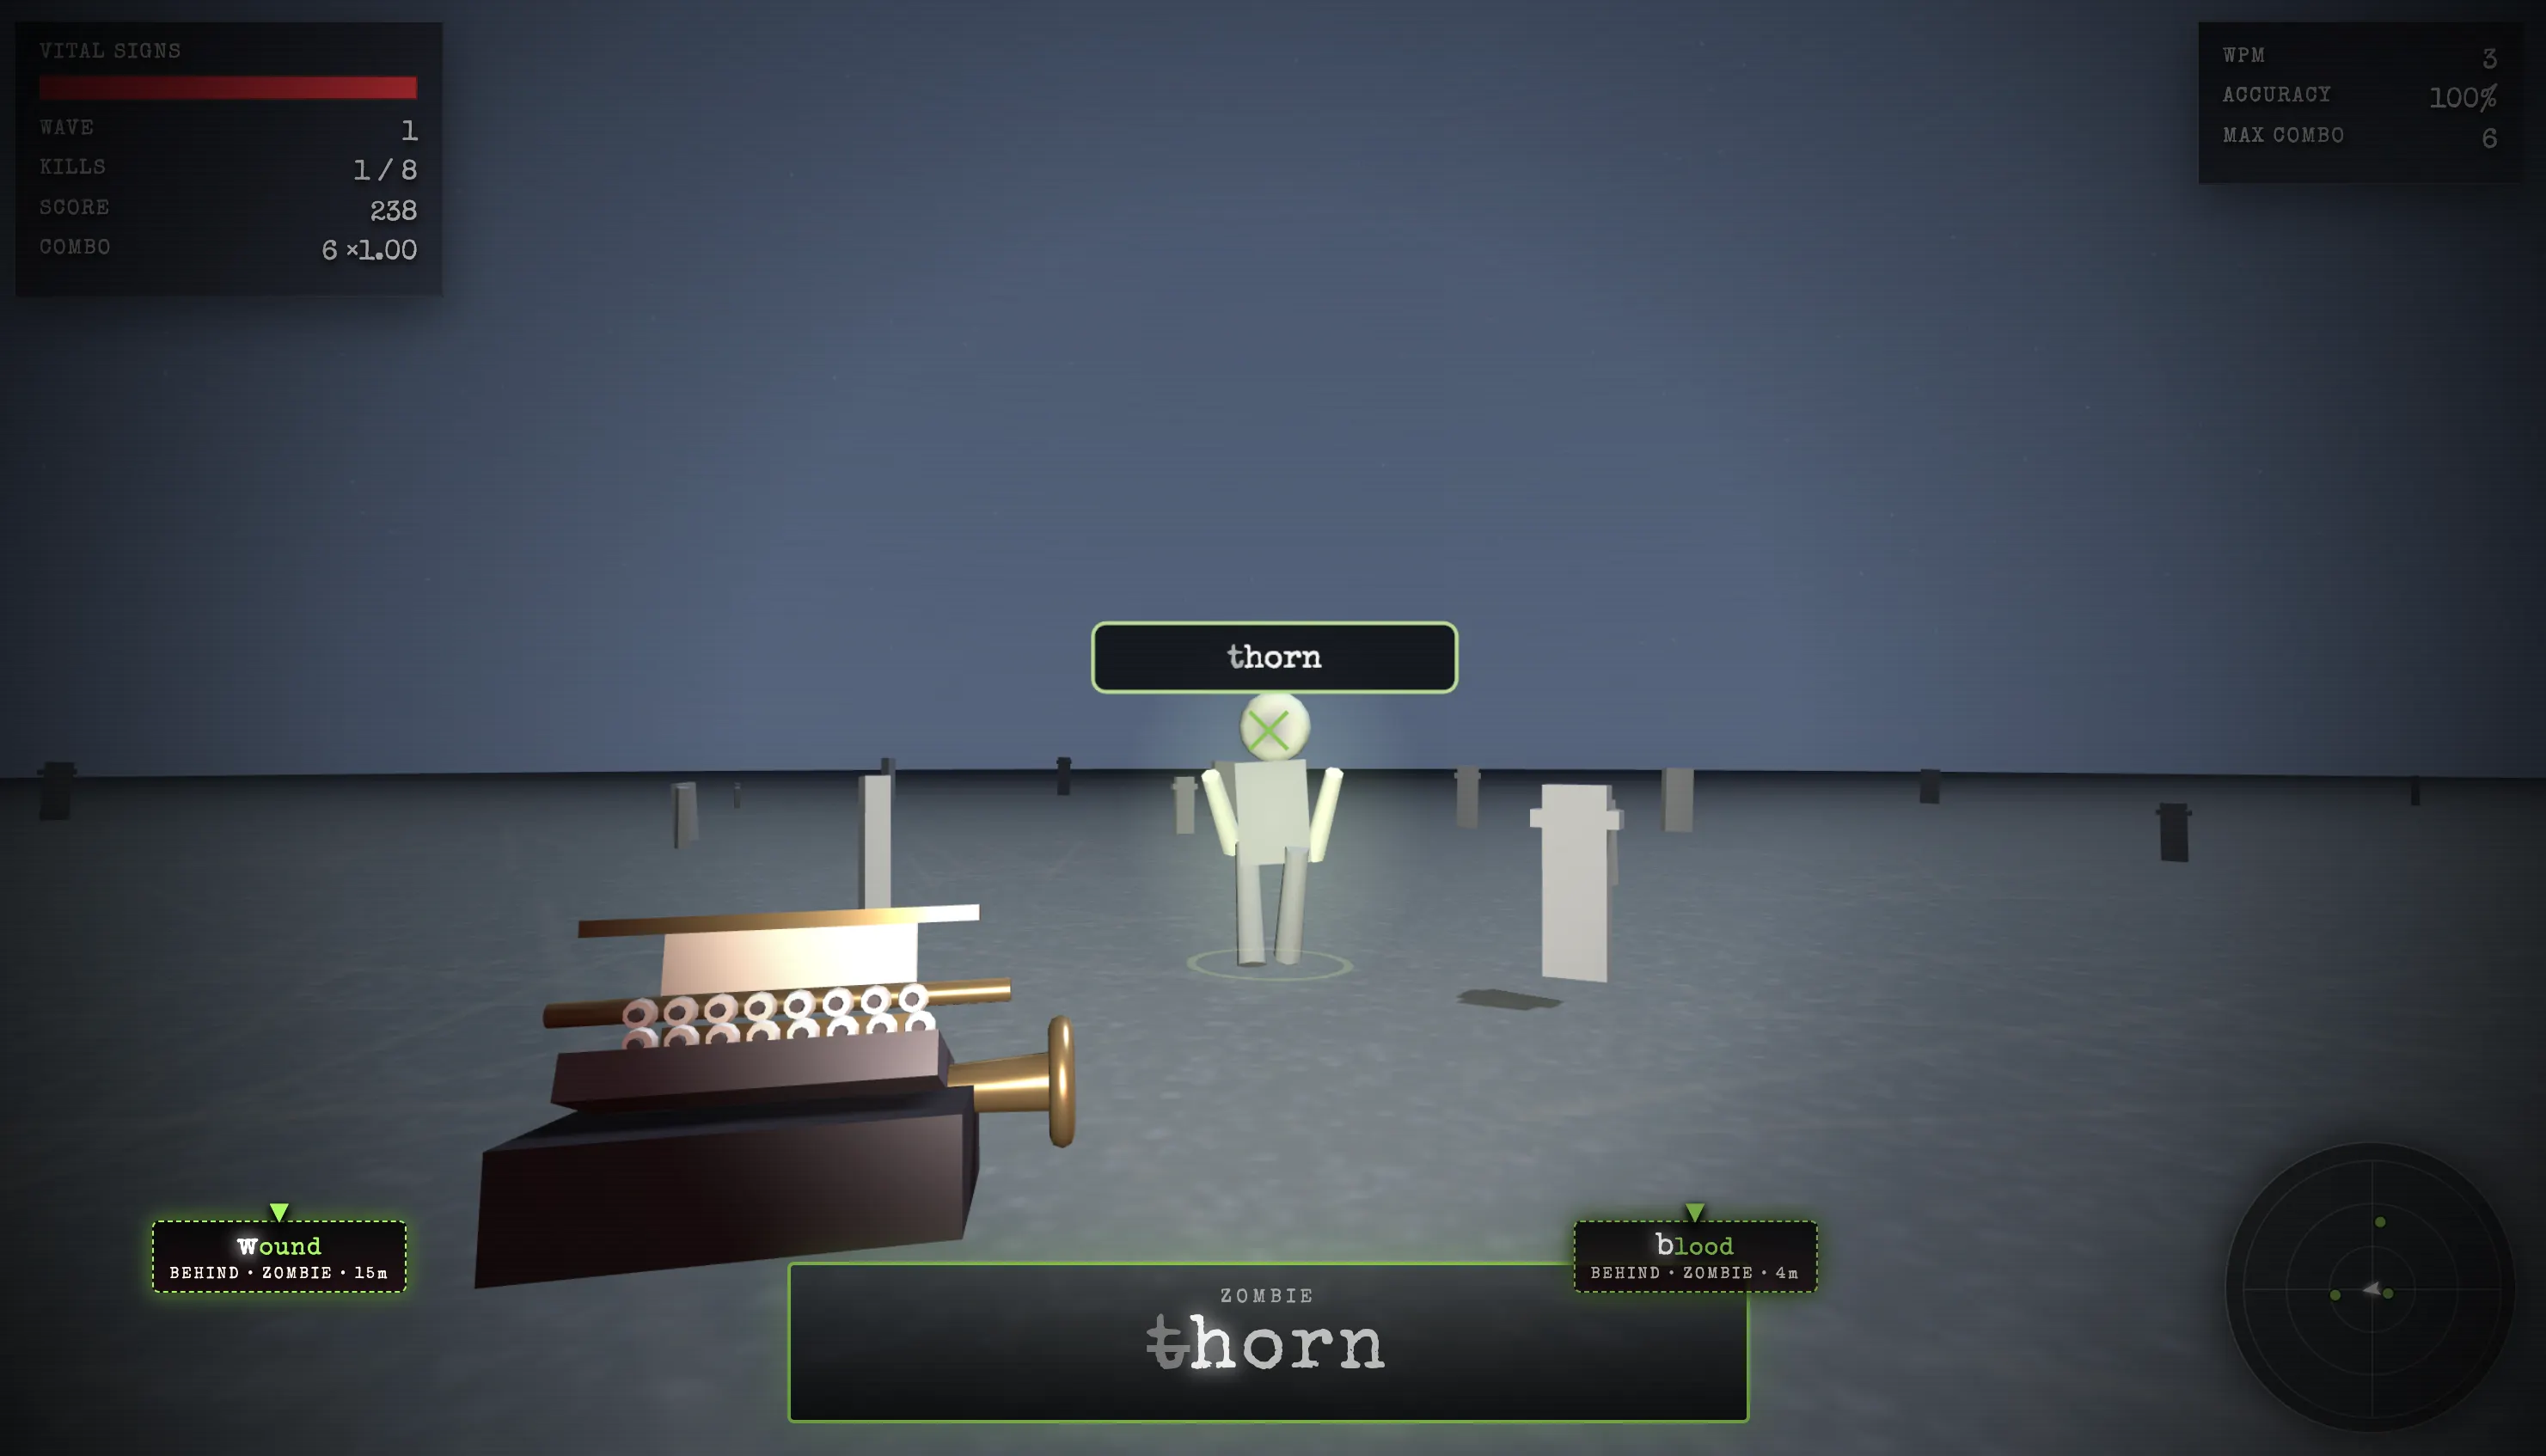
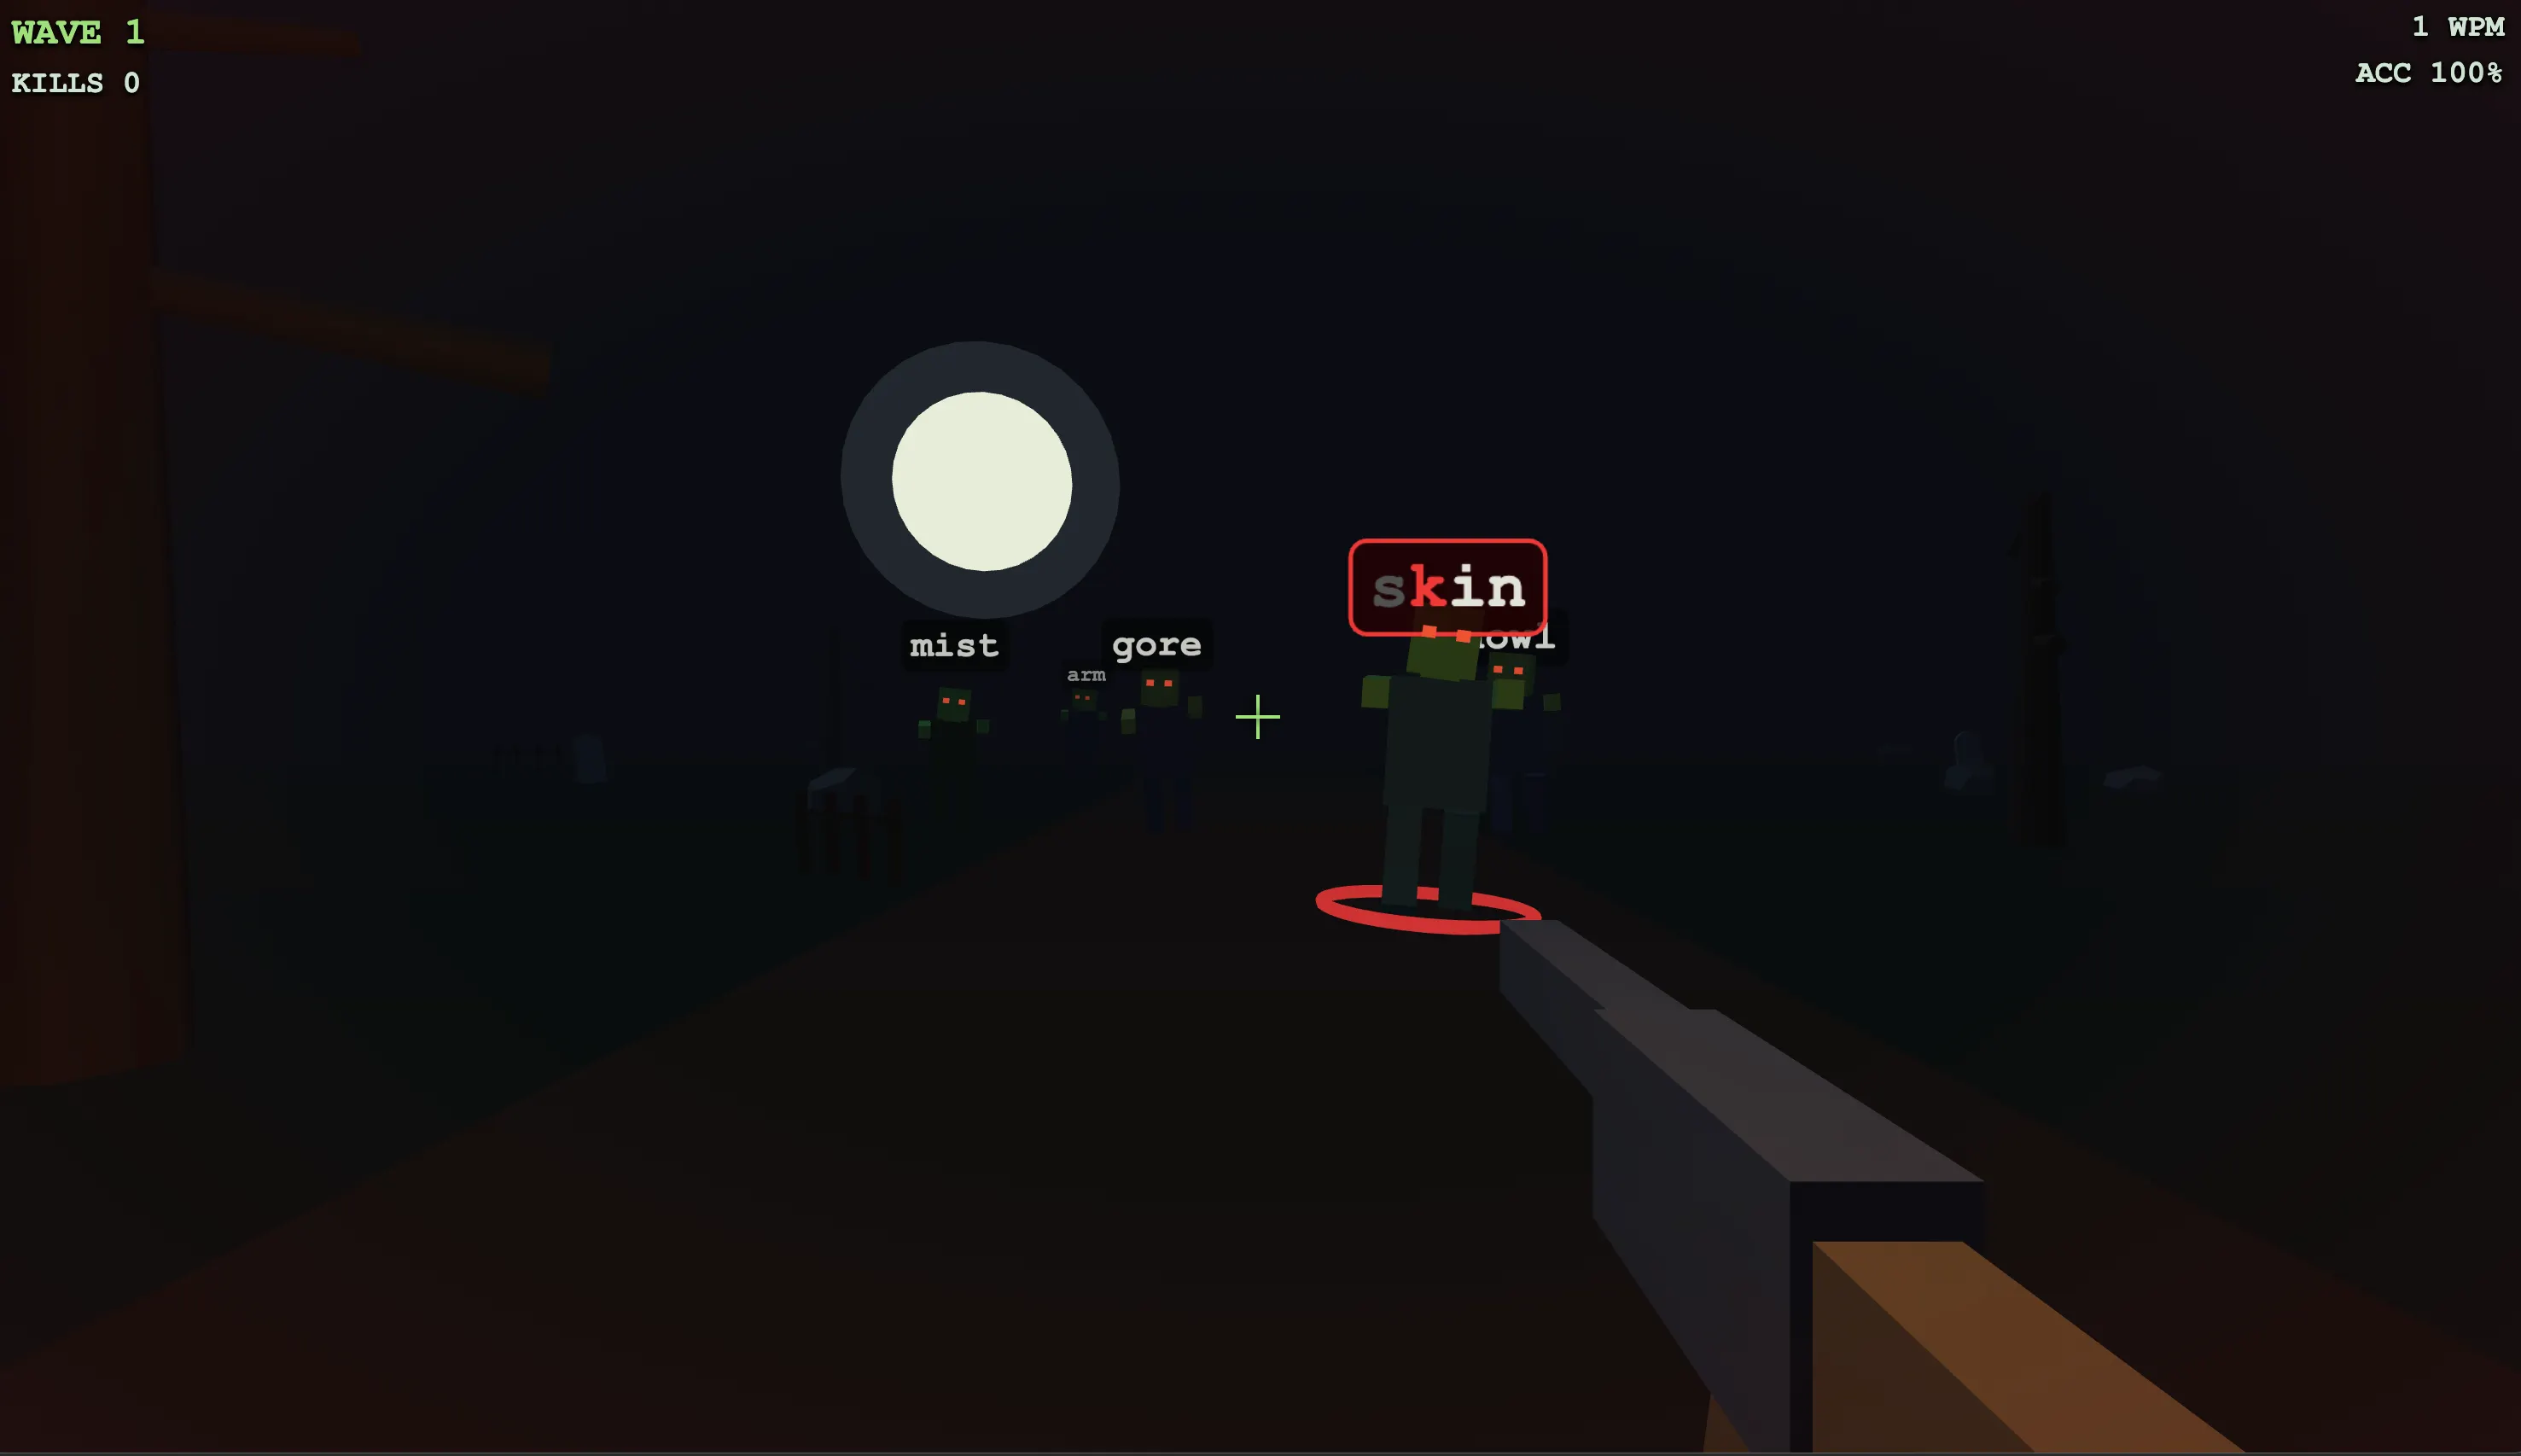
Coding: A one-shot browser game
Start every day with the top news stories right now, plus original features, a podcast, videos and more.
President Donald Trump’s command of U.S. financial and economic policy may have taken a step closer now that his Department of Justice has backed down from an investigation of Federal Reserve Chair Jerome Powell, meaning his nominee to replace Powell may now have an open path to confirmation.
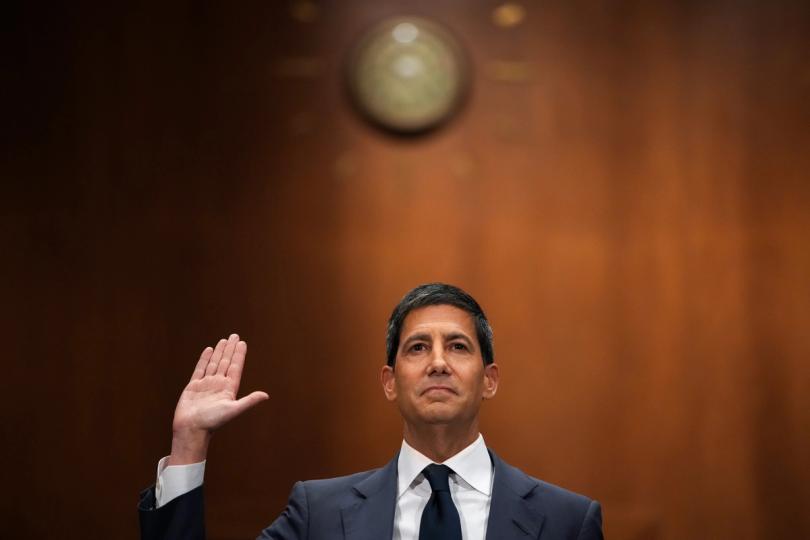
Fed chair nominee Kevin Warsh, whose own considerable wealth includes some crypto-world assets, is awaiting a final vote from the Senate after appearing in a confirmation hearing this week. Trump, who has relentlessly blamed Powell for maintaining overly high U.S. interest rates, chose Warsh to remedy that, but Republican Senator Thom Tillis had promised to block the confirmation as long as the DOJ pressed an investigation against Powell for cost overruns in a Fed building project.
That criminal probe was dropped on Friday, and Attorney General Jeanine Pirro said the DOJ asked the Fed’s inspector general to look into the renovation situation and issue a report. When the news emerged, Kalshi’s prediction betting on Walsh’s confirmation before May 15 shot up from about 30% odds to more than 80%.
“I expect a comprehensive report in short order and am confident the outcome will assist in resolving, once and for all, the questions that led this office to issue subpoenas,” Pirro wrote in a post on social media site X. “Accordingly, I have directed my office to close our investigation as the IG undertakes this inquiry. Note well, however, that I will not hesitate to restart a criminal investigation should the facts warrant doing so.”
Putting his own people atop the Federal Reserve not only equates with Trump’s greater influence over U.S. monetary policy, but it also leaves him with more allies on the Fed board as it makes decisions about financial policy — including implementing rules that govern the crypto industry and stablecoin issuers.
Because of Tillis’ threat, Warsh may have been in a holding pattern as long as the DOJ pursued its investigation, which could have left Powell in charge of the Fed indefinitely, well beyond the May 15 expiration of his term. Now, the Republican-majority Senate may be able to move more quickly toward confirmation of the nominee, who insisted during his hearing that he would act independently of White House direction.
Senator Elizabeth Warren, the ranking Democrat on the Senate Banking Committee that’s considering his nomination, dismissed the move and noted the administration is still pursuing Fed Governor Lisa Cook in court.
“This is just an attempt to clear the path for Senate Republicans to install President Trump’s sock pocket Kevin Warsh as Fed chair,” Warren said in a statement. “Let’s be clear what the Justice Department announced today: They threatened to restart the bogus criminal investigation into Fed Chair Powell at any time while failing to drop their ridiculous criminal probe against Governor Lisa Cook.”
Tillis called Warsh a “great nominee.” In his own posting this week on X, the senator said he’d vote yes on Warsh once the DOJ backs off of Powell:
“I look forward to supporting him out of committee once the DOJ drops their bogus investigation into Chairman Powell that threatens the independence of the Fed.”
This week, the Ethereum ecosystem has been rocked by a $654 million ETH transfer by the Ethereum Foundation. This triggered intense scrutiny over developer compensation, transparency, and leadership, culminating in the public resignation of core developer Péter Szilágyi and renewed criticism of governance practices.
Simultaneously, Polygon’s AggLayer upgrade has faced launch delays and network instability, intensifying debate about Layer-2 alignment, fragmentation, and the Foundation’s support for external L2s.
These developments, alongside POL token migration volatility, ongoing struggles to balance mainnet centralization with L2 sovereignty, and reaction to the Foundation’s earlier executive restructuring, have added fresh urgency to the disputes over Ethereum’s future direction and the sustainable growth of its scaling ecosystem.
Ethereum’s scaling architecture underwent a transformation from a technical sidebar to a political economy when Vitalik Buterin praised Coinbase’s Base for “doing things the right way,” weeks after Polygon founder Sandeep Nailwal assumed the CEO role at the Polygon Foundation, issuing warnings about Ethereum’s “existential” layer-2 (L2) direction.
The question emerging from competing visions is whether Ethereum will standardize how L2s earn and settle value, or watch liquidity fragment into parallel systems that route around rather than through the mainnet.
The tension crystallized across three developments in mid-2025. Nailwal took leadership of Polygon Foundation on June 11 amid a strategy reset, positioning the network as more independent from Ethereum’s rollup-centric orthodoxy.
Polygon shipped AggLayer v0.3 on June 23, advancing chain-agnostic interoperability with Polygon PoS, which was slated to connect by the end of the third quarter, but did not happen as of press time.
Buterin’s public endorsement of Base in September reignited debates over whether Ethereum’s leadership favors specific L2s, amplifying earlier friction when Nailwal questioned the low recognition from Ethereum core developers and warned that anti-L2 sentiment could fracture the ecosystem’s social fabric.
Data from L2BEAT shows Arbitrum and Base command the largest shares of value secured on Ethereum layer-2s, with OP Mainnet and Linea trailing.
The Polygon zkEVM remains materially smaller than its Proof-of-Stake chain, both in terms of total value locked and transaction activity.
Dune sequencer profit dashboards reveal that Base and Arbitrum generate the majority of net sequencer earnings after subtracting layer-1 data costs, with Base consistently ranking as a top profit generator through late summer 2025.
Buterin’s 2025 roadmap commentary centers on simplification, mainnet resilience, including privacy improvements, and a layer-2 user experience that relies more heavily on layer-1 security guarantees.
That guidance establishes what Ethereum leadership considers “good L2 citizenship”: canonical fraud or validity proofs, reliance on Ethereum for data availability, and alignment with emerging standards for light clients and shared sequencing.
Polygon’s AggLayer pursues chain-agnostic shared liquidity, positioning the network adjacent to, rather than inside, Ethereum’s rollup orthodoxy.
Its Proof-of-Stake chain is migrating toward zkEVM validium integration, which utilizes alternative data availability layers.
The next six to 12 months will test whether Ethereum can standardize value flows across competing layer-2 architectures.
In a soft-alignment scenario with a 50% to 60% probability, the Ethereum mainnet captures 25% to 40% of the layer-2 gross fee revenue as improvements in blob compression and data availability stabilize costs.
Base and Arbitrum retain 60% to 70% of layer-2 net profits, with OP Stack proliferation sustaining Base’s distribution advantage through Coinbase’s on-ramp infrastructure.
Polygon’s AggLayer connects its Proof-of-Stake ecosystem and CDK chains to drive cross-chain liquidity growth. Still, Ethereum-native transaction flows prioritize OP Stack clusters due to canonical settlement guarantees.
POL token performance in this scenario depends on the ecosystem’s breadth rather than rollup orthodoxy credentials.
A fragmentation scenario at 20% to 25% probability sees Ethereum mainnet data-availability revenue underperform as activity shifts to non-Ethereum DA layers, including validiums and alternative availability services.
Layer-1 captures only 15% to 25% of layer-2 gross fees, as competing liquidity centers, such as AggLayer, OP Superchain, and application-specific ZK rollups, split users across incompatible standards.
Maximal extractable value (MEV) smoothing across layer-2s lags technical deployment, worsening user experience during cross-rollup operations.
Polygon gains mindshare with chain-agnostic routing in this scenario, as Proof-of-Stake migration to AggLayer establishes a parallel liquidity hub that is partially decoupled from Ethereum’s social consensus mechanisms.
Re-convergence under Ethereum-first norms carries a 20% to 25% probability, driven by stronger layer-2 minimalism through the use of light clients, fault and validity proofs, and shared sequencing or proposer-builder separation, which also extends to rollups.
Mainnet captures 35% to 50% of layer-2 gross fees as infrastructure standards tighten. Base and Arbitrum consolidate over 70% of layer-2 profit share, with OP Stack standardization and cross-rollup bridging reducing friction for users moving assets between chains.
Polygon tightens Ethereum alignment through ZK proofs and Ethereum data-availability lanes for flagship chains while positioning AggLayer as a user-experience differentiator rather than a sovereignty play that competes with mainnet settlement.
Ethereum investors face a revenue-capture question tied directly to layer-2 architecture choices.
A higher reliance on Ethereum’s data availability (DA) and canonical proof systems increases mainnet fee capture, with blob utilization trends relative to layer-2 compression advances determining whether Ethereum’s toll-road economics expand or erode.
Cross-rollup MEV markets remain nascent, but if Ethereum-aligned proposer-builder separation norms extend to layer-2 sequencers, extractable value flows back to Ethereum validators. Alternative scenarios where MEV concentrates in layer-2 silos reduce the mainnet’s economic gravity.
Layer-2 tokens, including ARB, OP, and POL, derive their narratives from the profitability of the net sequencer, creating sensitivity to monthly profit leaderboards that show Base, operating without a native token, setting user-experience standards that pressure tokenized rollups to justify their value through revenue sharing, grants, or governance power.
Polygon’s investment case improves if AggLayer drives composability that converts to retained liquidity rather than transient bridge volume, independent of ranking as the largest pure rollup by orthodox definitions.
Monitoring AggLayer connection milestones and Proof-of-Stake migration progress provides leading indicators for this scenario.
Builders optimizing for distribution confront a pragmatic calculation where OP Stack and Base infrastructure win near-term user acquisition through streamlined on-ramps and L2 to L2 liquidity routing.
Teams prioritizing user experience and cross-chain operability may outperform those focused on doctrinal alignment debates, particularly as multichain user experiences remain challenging and network effects favor the largest distribution hubs.
Coinbase’s Base receiving public praise from Buterin sharpens debates over corporate influence versus Ethereum’s social fabric, particularly as global regulatory frameworks, including MiCA and FATF guidance, favor KYC-friendly L2s with clear operational entities.
Polygon’s chain-agnostic AggLayer vision competes with OP Superchain and ZK rollup hubs in an interoperability arms race analogous to mobile platform competition, where walled gardens are contrasted with open liquidity meshes.
The Ethereum mainnet is positioned as foundational infrastructure rather than an exclusive settlement layer.
User gravity concentrates in networks that solve multichain pain points, with Vitalik and Ethereum core researchers pushing for a simplified, layer-1-secured L2 user experience.
If user-experience standards unify around common light-client implementations and proof verification, network effects compound advantages for the largest distribution hubs, including Base and Arbitrum.
Polygon’s alternative path depends on AggLayer establishing sufficient cross-chain liquidity, enabling developers and users to opt for composability over canonical Ethereum settlement.
The outcome determines whether Ethereum operates as a standardized settlement layer capturing predictable fees from aligned rollups, or as one option among competing architectures where liquidity and users distribute across networks with varying degrees of mainnet dependency.
Sequencer profit concentration, blob utilization rates, and AggLayer adoption metrics through mid-2026 will clarify which path the ecosystem follows, and whether loyalty to Ethereum becomes a measurable economic parameter rather than a social-layer assumption.


